OpenZhenZhen AI Prompt Gallery · Moss Image · image
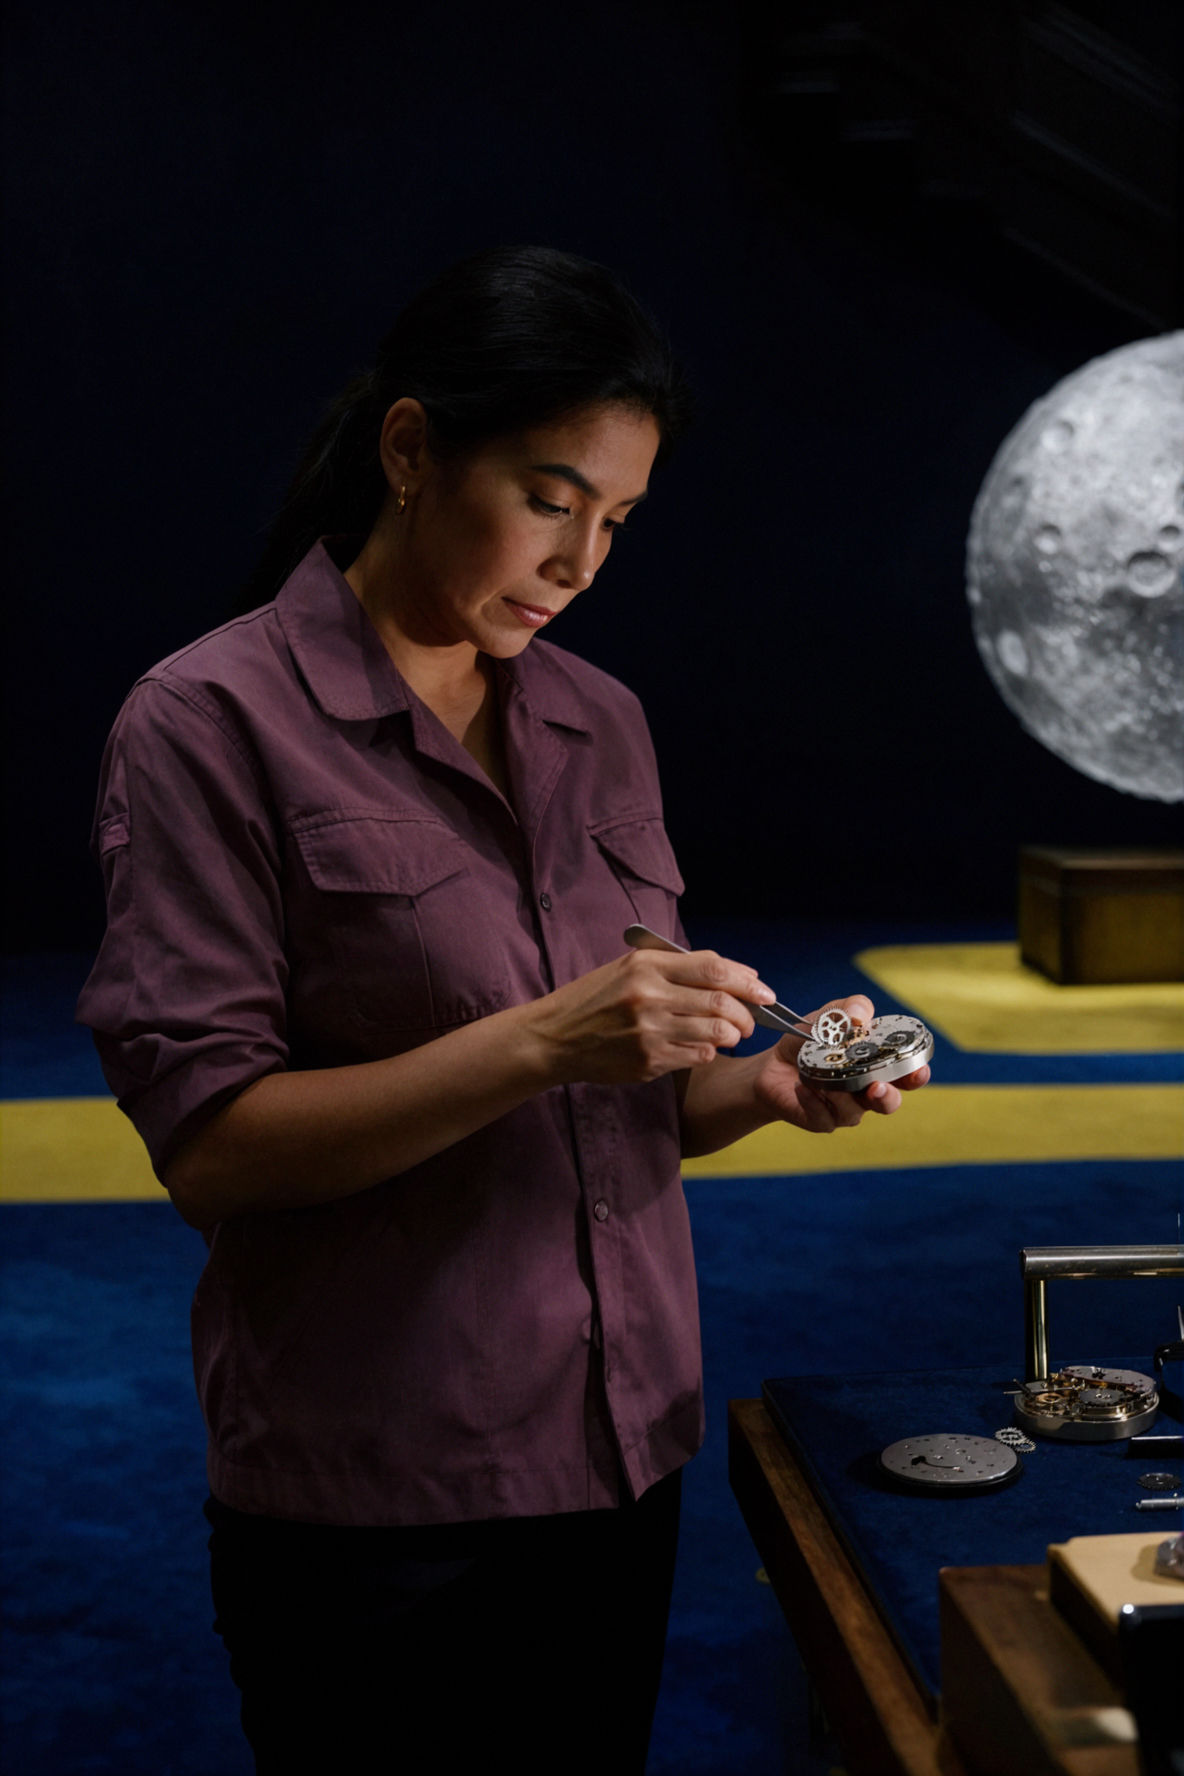
Adult Latina Watchmaker · Gears in Place · Understated Rembrandt
Adult Latina Watchmaker · Gears in Place · Understated Rembrandt — explore this Moss Image creation on OpenZhenZhen, with its original prompt and a reusable generation example.
Prompt
Chinese prompt
创作一张富有观赏性的「低调伦勃朗」完整照片:成年拉丁裔女性钟表匠,身穿灰紫工作衬衫,正在以镊子将微小齿轮放入敞开机芯。场景:有银色月球装置的空旷大厅,仅配备明确活动实际需要的工具。一位衣着得体的主要成年人,面容自然有神,身体结构连贯,手势符合所做工作。双手应实际执行点名活动并与道具清楚接触,保留指定身体姿态,不替换为正对镜头的人像摆拍。摄影:85毫米低调伦勃朗布光,小三角面颊光与天鹅绒暗部。构图:三分之四全景,对角运动、前进方向留有空间。环境点缀配色:钴蓝与柠檬黄点缀,保留主角经典固有色。捕捉一个具体、有情节、动作可读的关键瞬间,不采用通用站桩姿势。面向网站图库缩略图,设置鲜明唯一主角、清爽轮廓、清楚面容、克制背景细节及有意义的前后景纵深。动作道具与必要肢体完整入画,动作需要时优先放宽景别。重量、接触、双手、衣料运动和反射应可信。电影摄影完成度,独立单幅,不要分格、字幕或水印。
English prompt
Create a visually striking finished low-key Rembrandt portrait photograph: an adult Latina woman watchmaker, wearing a muted plum work shirt, actively placing a tiny gear into an open watch movement with tweezers. Location: a spacious hall with a silver moon installation; include only the tools actually required by the specified activity. One principal appropriately dressed adult, expressive natural face, coherent anatomy and task-specific hands. The hands must actually perform the named activity, with visible contact to its prop; preserve the specified body posture instead of replacing it with a camera-facing portrait. Photography: 85mm lens, a small triangular cheek highlight, velvety dark background. Composition: three-quarter full view with diagonal movement and deliberate breathing room ahead. Environmental accent palette: cobalt blue with lemon-yellow accents; retain canonical subject colors. Capture one specific story moment at the peak of a readable gesture, not a generic stock standing pose. For a website gallery thumbnail, establish one strong focal subject, a clean silhouette, clear face, restrained background detail and meaningful foreground-to-background depth. Keep the action prop and essential limbs within the frame; use a wider view if the chosen action requires it. Resolve weight, contact, hands, fabric motion and reflections convincingly. Photographic cinematic finish, one image, no panels, captions or watermark.
Topics and styles
Explore more AI image and video prompts · Try image generation · Try video generation · Create on the AI canvas
Related works
- Adult Latina Watchmaker · Gears in Place · Infrared False Color
Adult Latina Watchmaker · Gears in Place · Infrared False Color — explore this Moss Image creation on OpenZhenZhen, with its original prompt and a reusable generation example.
- Roronoa Zoro · Swift Turn in the Woods · Understated Rembrandt
Roronoa Zoro · Swift Turn in the Woods · Understated Rembrandt — explore this Moss Image creation on OpenZhenZhen, with its original prompt and a reusable generation example.
- Adult Middle Eastern Woman Book Restorer · Binding and Threading · Understated Rembrandt
Adult Middle Eastern Woman Book Restorer · Binding and Threading · Understated Rembrandt — explore this Moss Image creation on OpenZhenZhen, with its original prompt and a reusable generation example.
- Adult Latina Watchmaker · Pocket Watch in Light · Old Mirror Swirl Focus
Adult Latina Watchmaker · Pocket Watch in Light · Old Mirror Swirl Focus — explore this Moss Image creation on OpenZhenZhen, with its original prompt and a reusable generation example.
- Takashi Natsume · Paper Lanterns in the Wind · Understated Rembrandt
Takashi Natsume · Paper Lanterns in the Wind · Understated Rembrandt — explore this Moss Image creation on OpenZhenZhen, with its original prompt and a reusable generation example.
- Ichigo Kurosaki · Swift Turn in the Woods · Prismatic Refraction
Ichigo Kurosaki · Swift Turn in the Woods · Prismatic Refraction — explore this Moss Image creation on OpenZhenZhen, with its original prompt and a reusable generation example.